
Improving Inter-Rater Reliability When Multiple Teachers Score the Same Essay
Published on October 13th, 2026 by the GraideMind team
Give the same essay on The Long Earth to five teachers and you may well receive five different scores. Differences arise from personal preferences, mood, fatigue, and unwritten standards. Researchers call the degree of agreement among scorers inter-rater reliability, and improving it is a practical goal for any department.
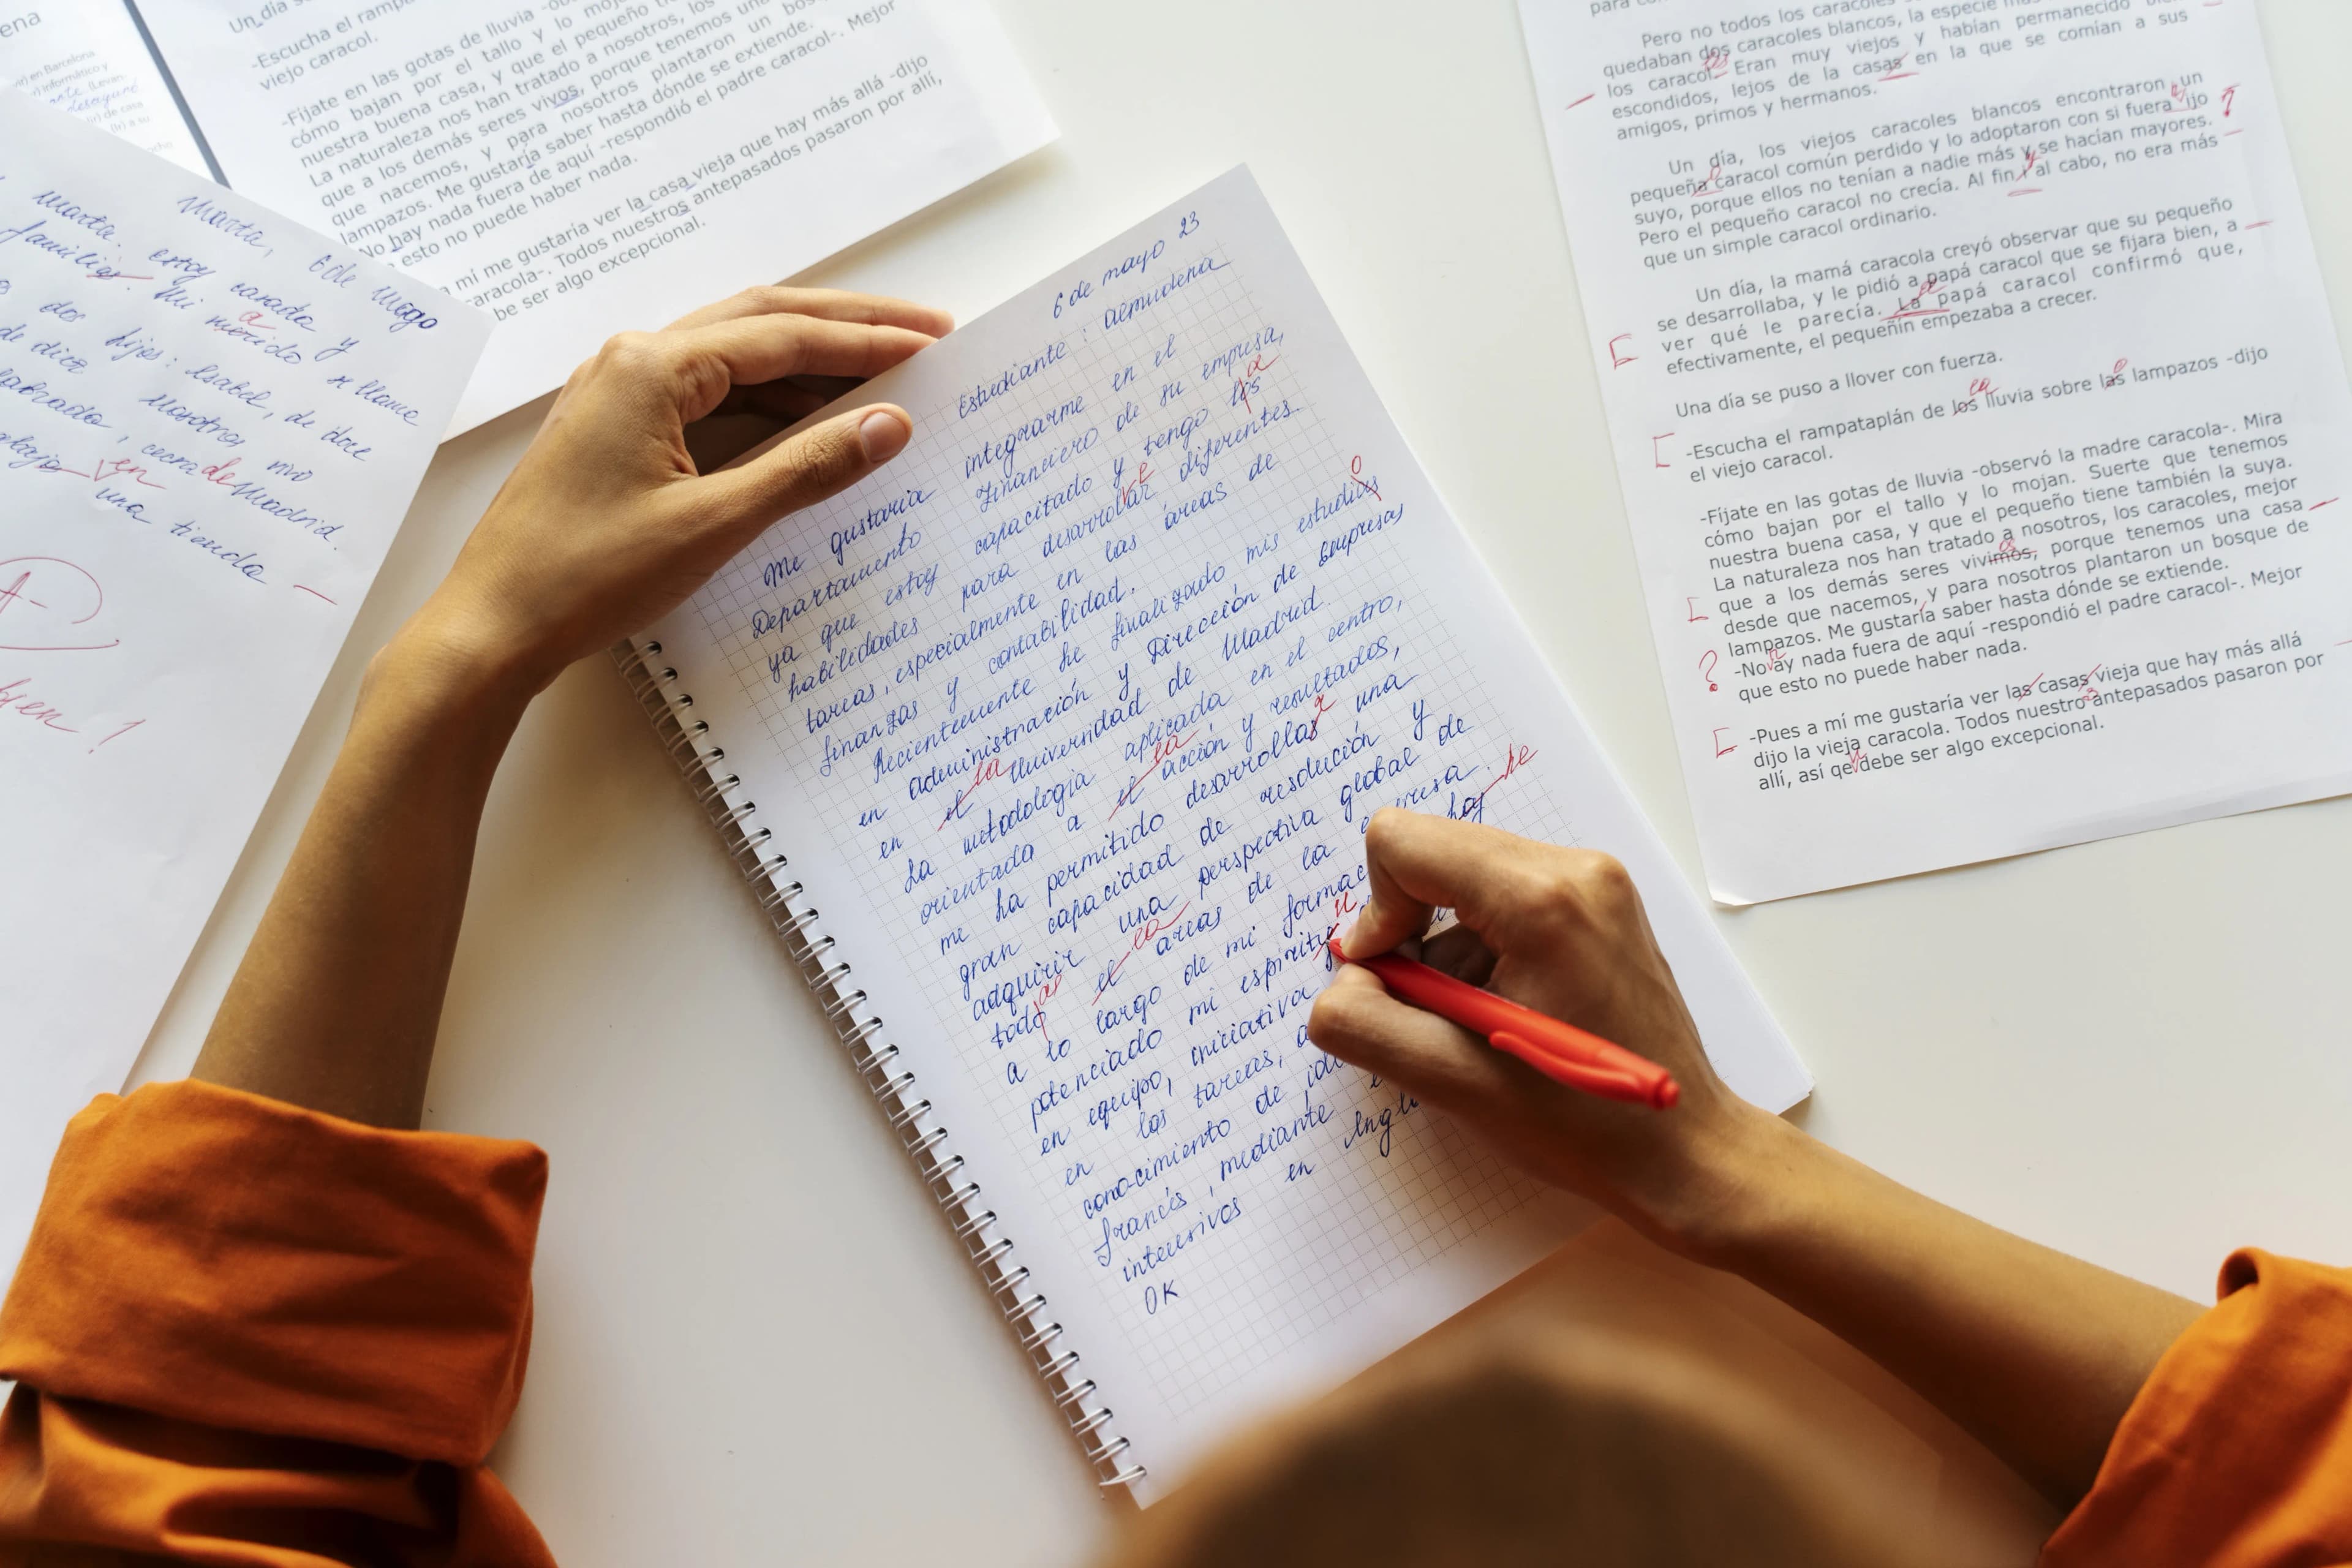
Low reliability harms students, since two classmates with similar work may receive different grades depending on who reads their paper. It also complicates efforts to use scores for evaluation or program decisions. Even modest improvements in consistency make assessment data more trustworthy.
The most effective single practice is calibration: scoring shared sample essays independently and then comparing results. When teachers discuss why they scored an essay differently, they discover which criteria are ambiguous and which are interpreted loosely. These discussions lead directly to better rubrics.
A simple calibration protocol
A protocol need not be elaborate. Choose three essays that represent high, middle, and low performance, and have each teacher score them in silence. Then record the scores on a board, discuss the largest gaps, and revise the descriptors that caused them.
- Select three sample essays from a prior year with names removed
- Score independently before any discussion takes place
- Record every score and note the criterion with the widest spread
- Discuss specific evidence in the essay that supported each score
- Rewrite the unclear descriptor and rescore a fourth essay to test the change
Agreement improves when teachers argue about evidence rather than impressions.
Stop spending your evenings grading essays
Let AI generate rubric-based feedback instantly, so you can focus on teaching instead.
Try it free in secondsCommon sources of disagreement
Frequent causes include differing views of what counts as sufficient analysis, whether to penalize errors that do not obscure meaning, and how to treat well-written but shallow essays. Identifying which of these is at work guides the revision. Often a single clarifying phrase resolves much of the disagreement.
Halo effects also play a role. An essay with a strong introduction may receive higher scores across criteria than it deserves. Reading criterion by criterion, rather than forming one overall impression, reduces this bias.
Using data to monitor reliability
Track agreement by double-scoring a random ten percent of essays and comparing results. If scores differ by more than one level on a four-point scale, flag the essay for discussion. This light-touch audit identifies problems without requiring everyone to score everything twice.
A rubric-based AI reader can serve as a consistent additional rater, providing a reference score for each essay. Teachers compare the reference with their own, and investigate where differences are large. The aim is not to replace human judgment but to make inconsistencies visible.
Sustaining the practice
Calibration works best when it is routine, built into the schedule before major grading periods. Teachers are more willing to participate when sessions are short and focused on a concrete outcome. Keeping a library of scored exemplars saves time in future years.
Share results with the department to show progress. When teachers see that agreement has improved, they recognize the value of the effort. Over time, the culture shifts toward treating grading as a shared professional practice.
See how fast your grading workflow can be
Most teachers go from hours per batch to minutes.
Create free account