
How History Departments Can Calibrate Grading on Interpretive Essays Like Hofstadter's
Published on October 13th, 2026 by the GraideMind team
Interpretive essays, such as those based on Hofstadter's The American Political Tradition, are especially prone to scoring inconsistency. Two teachers can read the same essay and disagree about whether its argument is persuasive or merely competent. When grading standards vary across a department, students feel the unfairness, and parents may begin to question grades. Calibration sessions give teachers a structured way to align their standards without erasing their individual judgment.
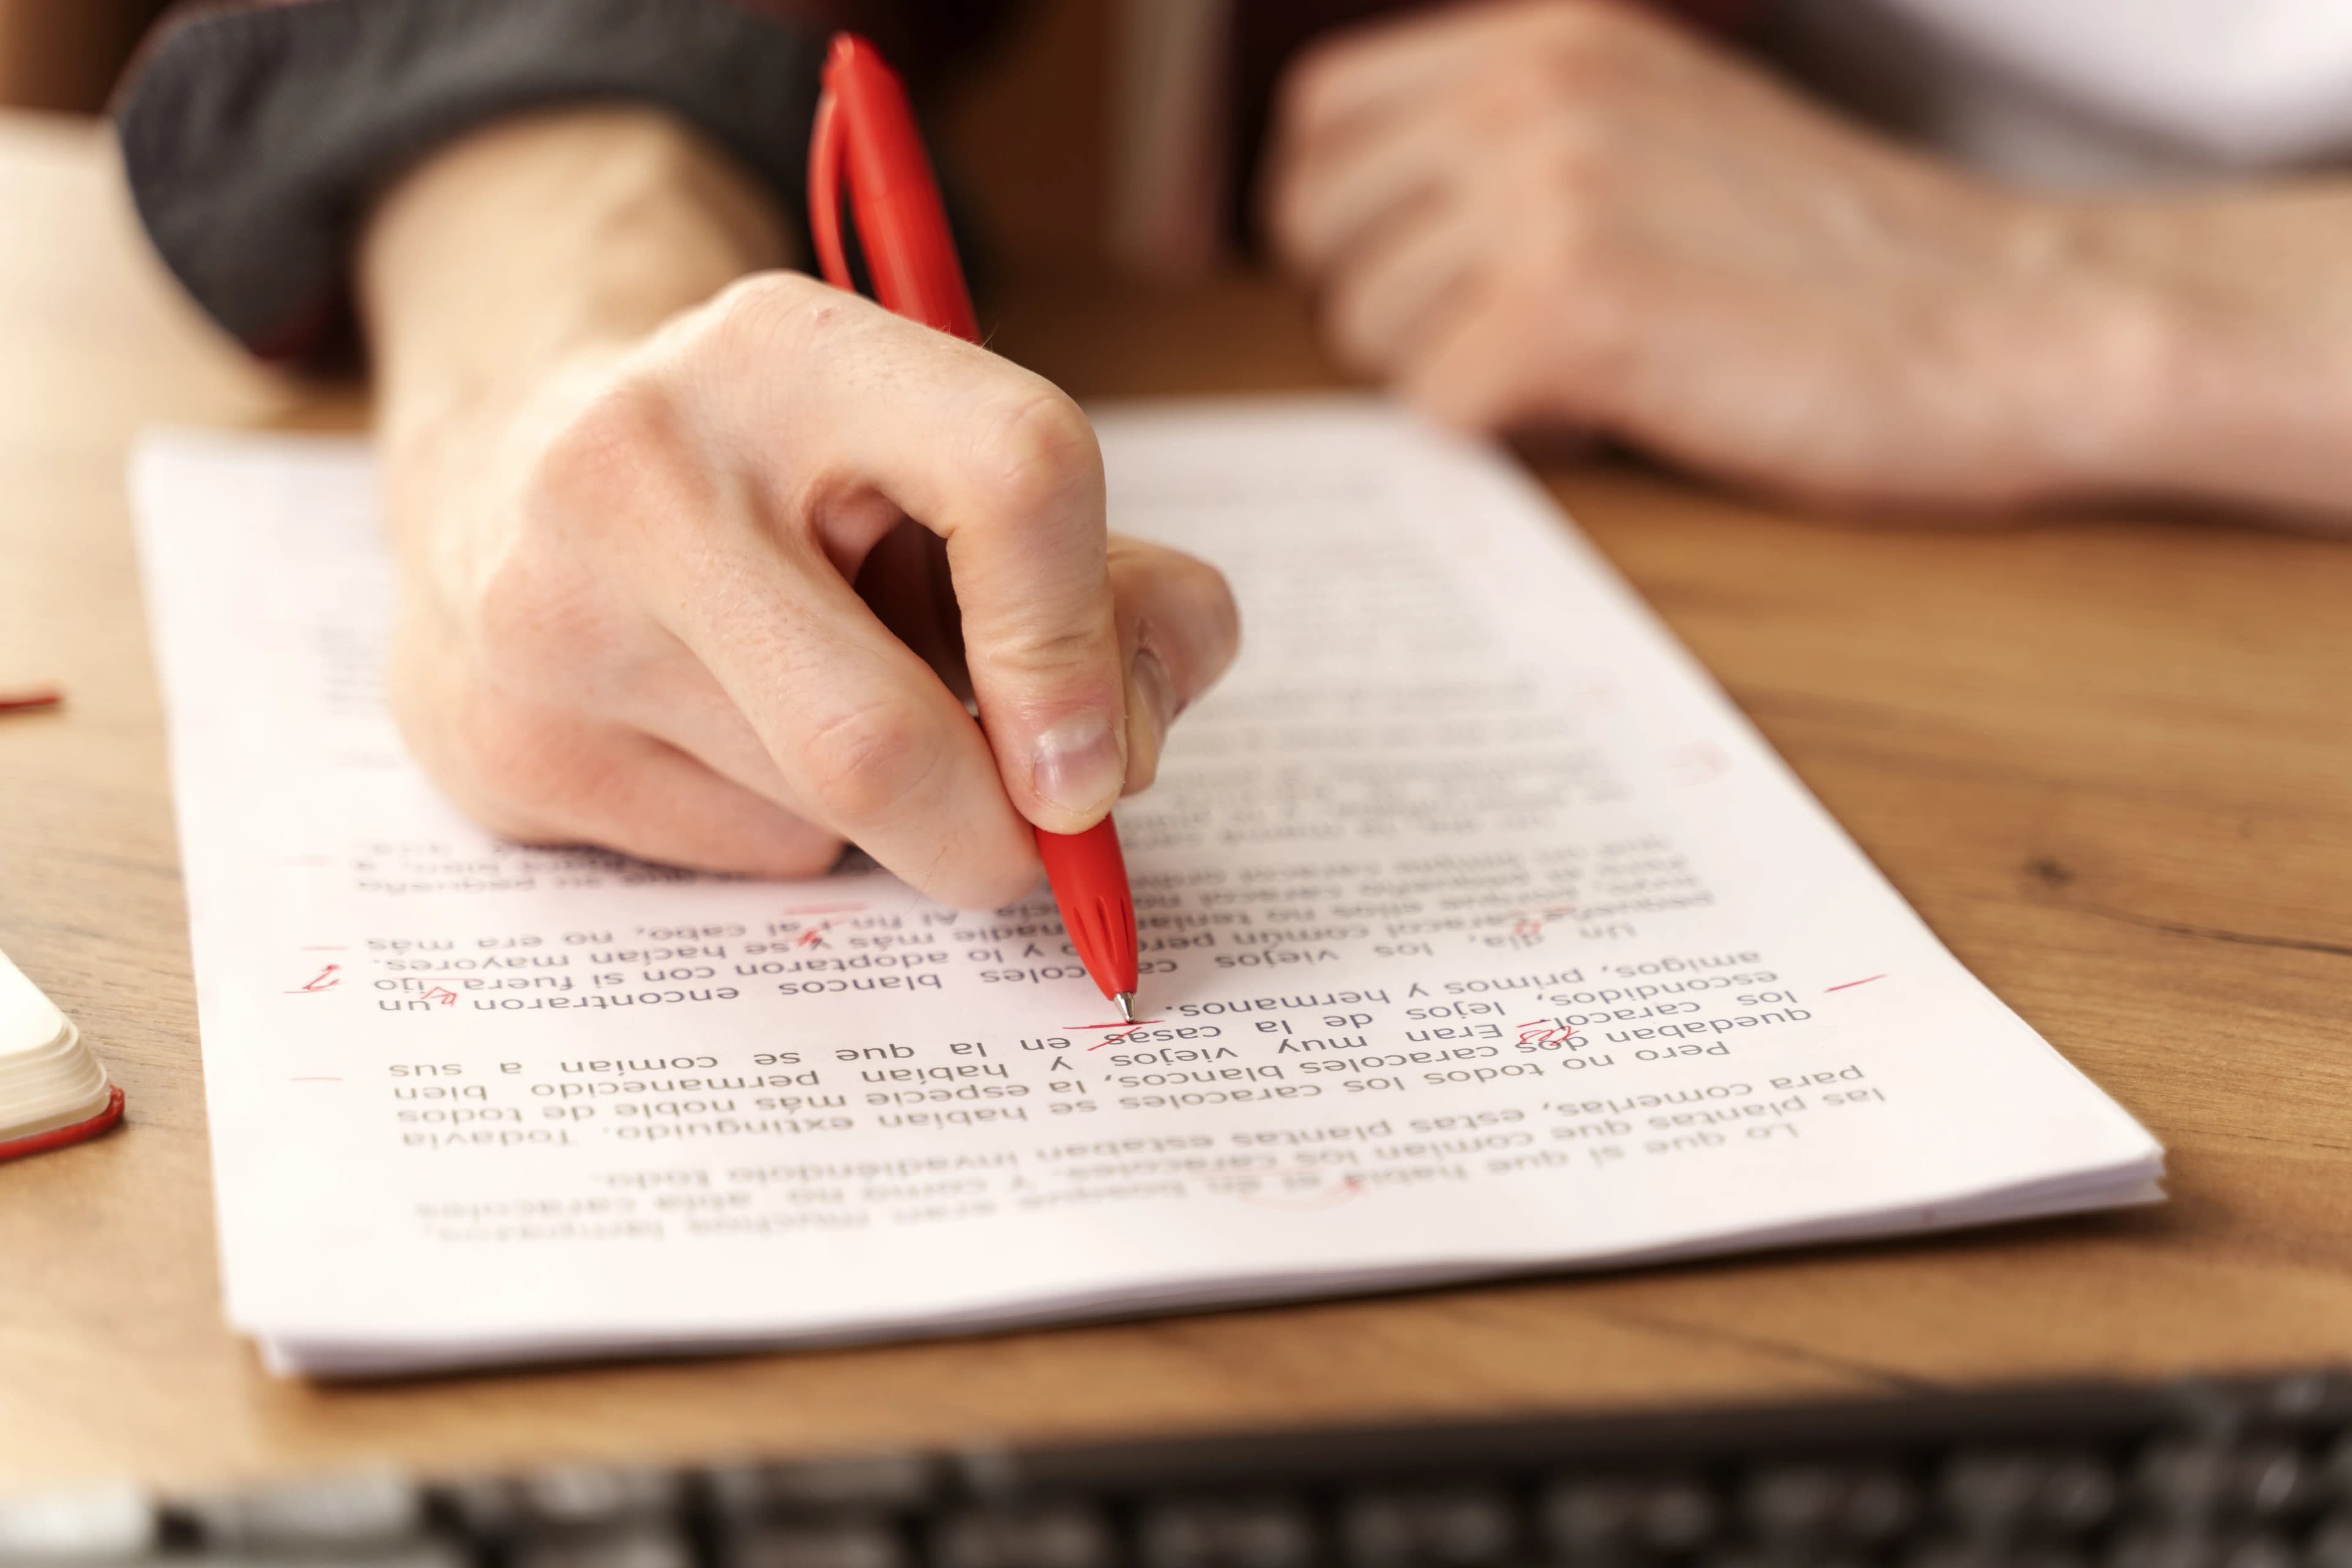
A calibration session begins with a shared set of sample essays that represent a range of quality. Each teacher scores them independently using the common rubric, without discussing them in advance. The group then compares scores and talks through the differences, focusing on the specific language in the essays that led to each decision. These conversations reveal where the rubric is ambiguous and where teachers hold different assumptions.
The most valuable outcome is a set of anchor papers that the department agrees exemplify each score level. Teachers can then refer to these anchors throughout the grading period to check their own consistency. Anchors also help new teachers understand local standards quickly. Over the years, a library of anchors becomes one of the department's most useful shared assets.
Running an Effective Norming Session
Keep the session short and focused, ideally under an hour. Choose three to five essays that illustrate different levels and include at least one borderline case. Ask each teacher to share their score and the single most influential reason for it before open discussion begins. This sequence prevents dominant voices from anchoring the group and ensures that all perspectives are heard.
- Select sample essays that span the score range and include one deliberately ambiguous paper.
- Have each teacher score independently before any group discussion.
- Discuss disagreements by pointing to specific sentences, not general impressions.
- Revise rubric descriptors that caused repeated confusion during the session.
- Save the agreed anchor essays and notes for use in future terms.
Consistency across classrooms is a form of fairness that students can feel even if they cannot name it.
Stop spending your evenings grading essays
Let AI generate rubric-based feedback instantly, so you can focus on teaching instead.
Try it free in secondsSpecific Challenges With Interpretive Essays
Interpretive essays are harder to calibrate than fact-based assessments because the quality of an argument is partly subjective. Teachers may disagree about whether an unconventional reading of Hofstadter is insightful or just unsupported. The rubric can help by focusing on the reasoning and evidence rather than the conclusion. When the criteria emphasize how well a claim is supported, disagreement about the conclusion matters less.
Another challenge is the influence of writing style. Polished prose can create an impression of strong thinking even when the argument is shallow. Calibration discussions should explicitly address this tendency and remind teachers to separate content from fluency. Grading rubric rows independently, rather than forming a holistic impression first, helps counteract the halo effect.
Maintaining Calibration Over Time
Calibration is not a one-time event. Teachers drift in their standards as they grade more essays, and new members join the department. Plan to revisit the anchors at least once per term and whenever the rubric changes. A brief refresher before each major grading cycle keeps everyone aligned.
Mid-grading spot checks can also help. Have teachers swap a few essays and score them blind, then compare results. Large discrepancies point to areas where the rubric or the shared understanding needs attention. These small checks catch problems early and avoid the stress of regrading after grades are posted.
Where AI Grading Support Fits In
AI grading assistance can reinforce calibration by applying the same rubric language to every essay it reviews. A department can use it as a neutral reference point, comparing teacher scores with suggested scores and discussing any gaps. The comparison does not decide who is right, but it highlights where standards may be drifting. Teachers remain responsible for final scores, informed by both the tool and their professional expertise.
Departments considering such tools should pilot them on a small set of essays and review the results together. Look for consistency with your anchors, clarity of comments, and the ability to customize rubric criteria. Share findings openly so that all teachers understand how the tool is used. Transparent adoption builds trust and ensures that the technology supports the department's goals rather than reshaping them.
See how fast your grading workflow can be
Most teachers go from hours per batch to minutes.
Create free account